Hidden Execution Paths
Python services often run through layers of frameworks, middleware, and background workers. Critical execution paths disappear in production, leaving teams unsure how requests actually flow under real traffic.
Get end-to-end visibility into your Python performance with application monitoring tools. Gain insightful metrics on performance bottlenecks with Python monitoring to optimize your application.
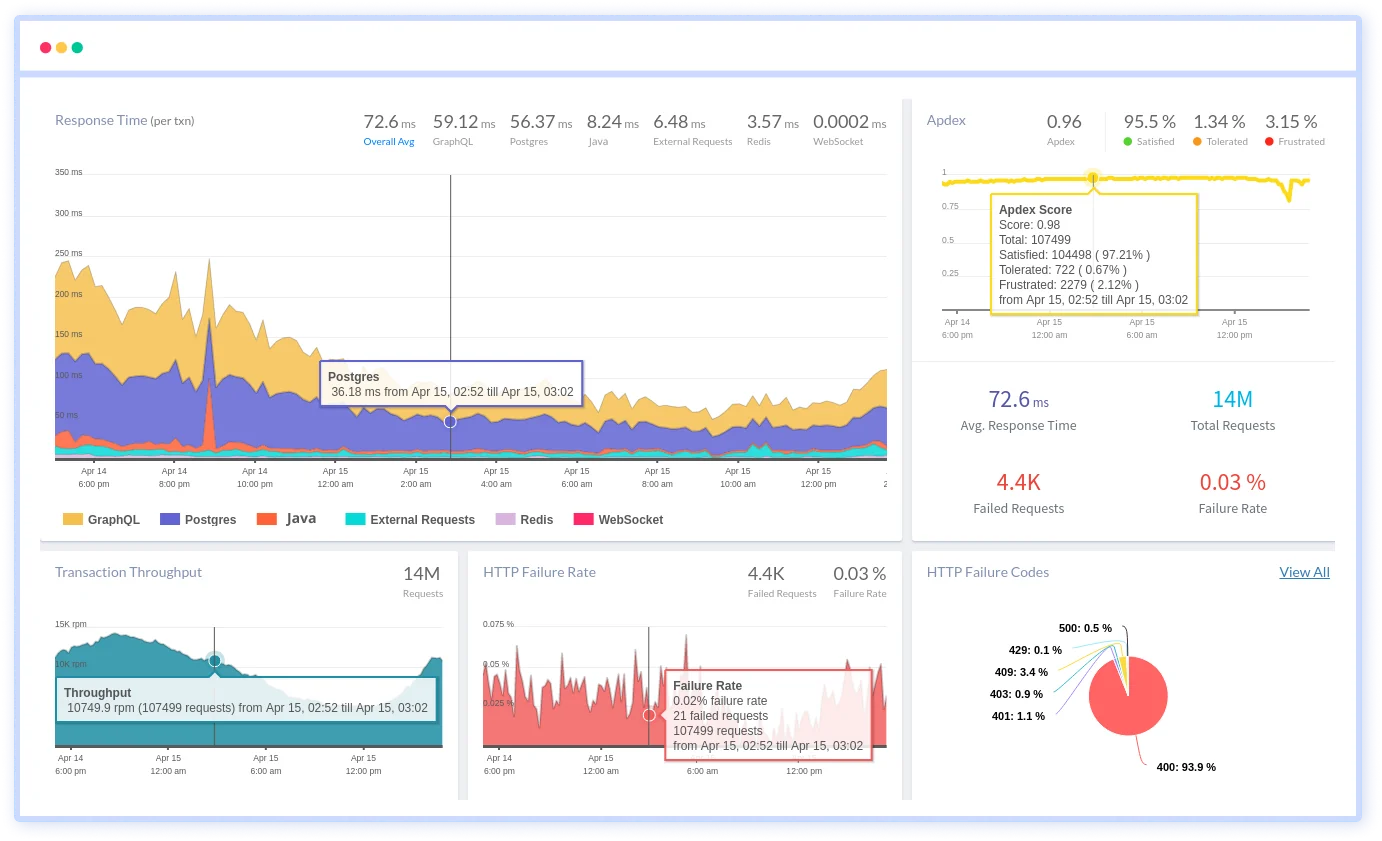
Python services often run through layers of frameworks, middleware, and background workers. Critical execution paths disappear in production, leaving teams unsure how requests actually flow under real traffic.
When incidents hit, engineers jump between logs, metrics, and assumptions. Correlating symptoms to a single cause takes too long, especially when failures cascade across services.
Event loops, coroutines, and task queues introduce behavior that is hard to reason about after deployment. Timing issues surface only at scale, without clear signals explaining why.
Code that works at low volume behaves differently under load. Memory growth, thread contention, and worker saturation emerge suddenly, often without obvious early warnings.
Production errors are rarely clean exceptions. Partial failures, retries, and timeouts blur the signal, making it difficult to separate real faults from background noise.
In shared platforms, it is unclear which team owns a slowdown or failure. Without precise context, incidents turn into handoff loops instead of fast resolution.
Differences between local, staging, and production environments hide critical behavior. Subtle config or dependency changes surface only when users are already impacted.
Repeated incidents without clear explanations reduce trust in the system. Teams start shipping more cautiously, slowing delivery to avoid unknown risks.
Real-time observability built for Python workloads to help teams diagnose issues faster, optimize execution, and maintain reliable production systems.
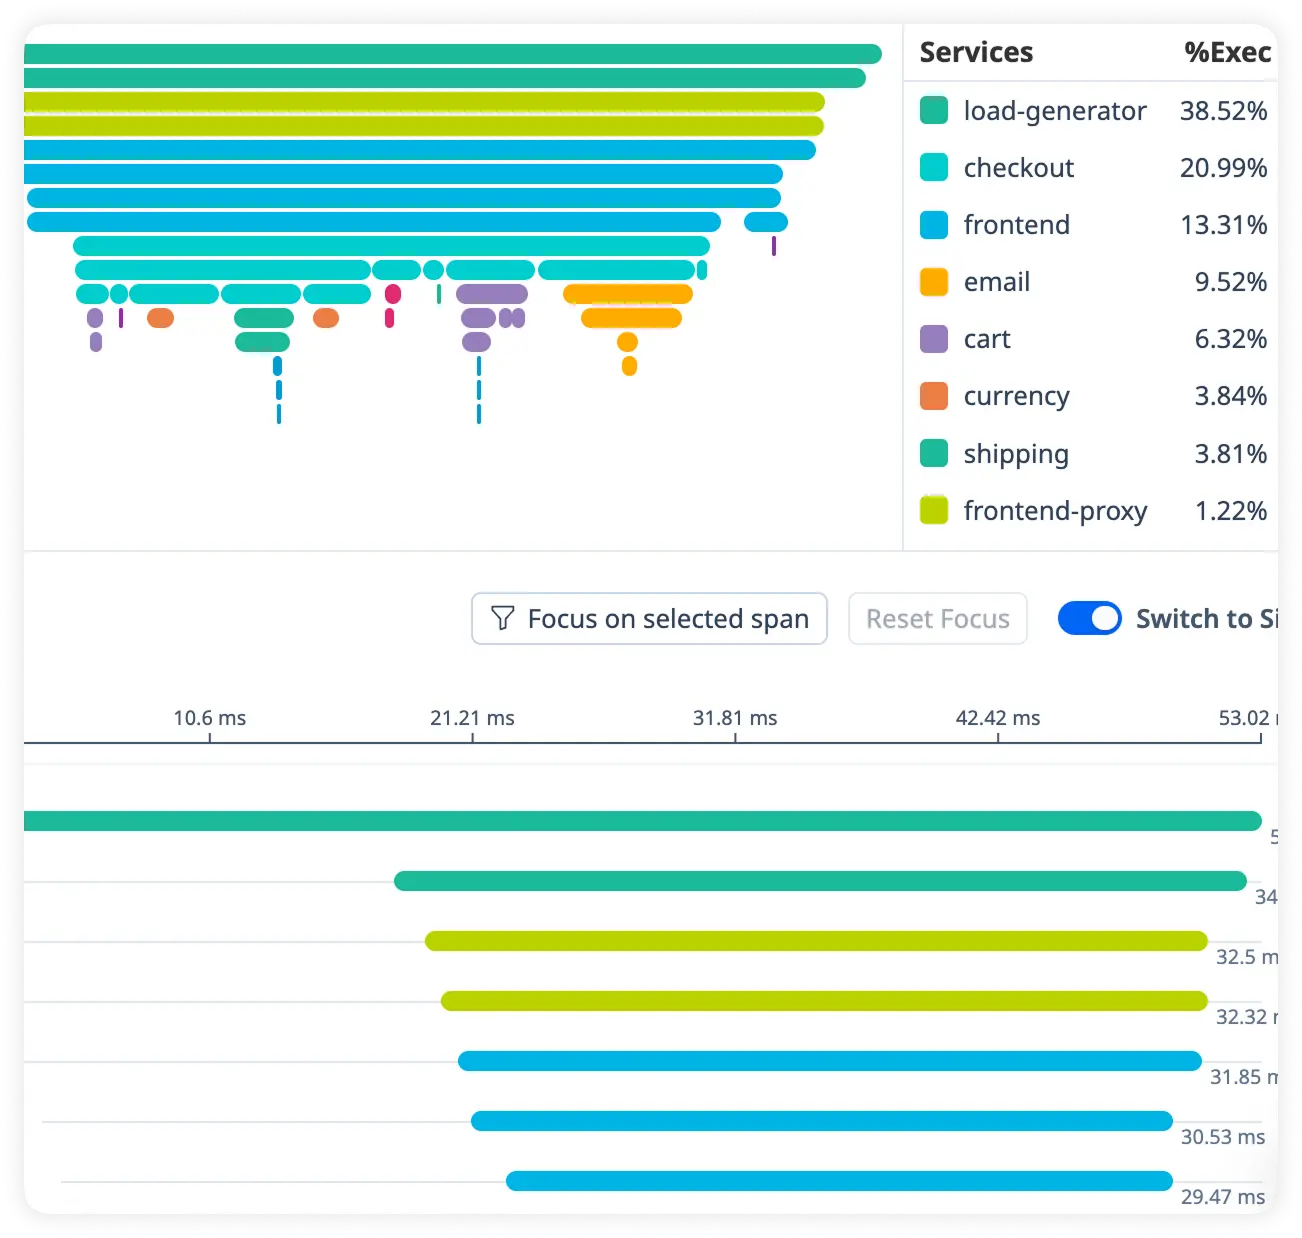
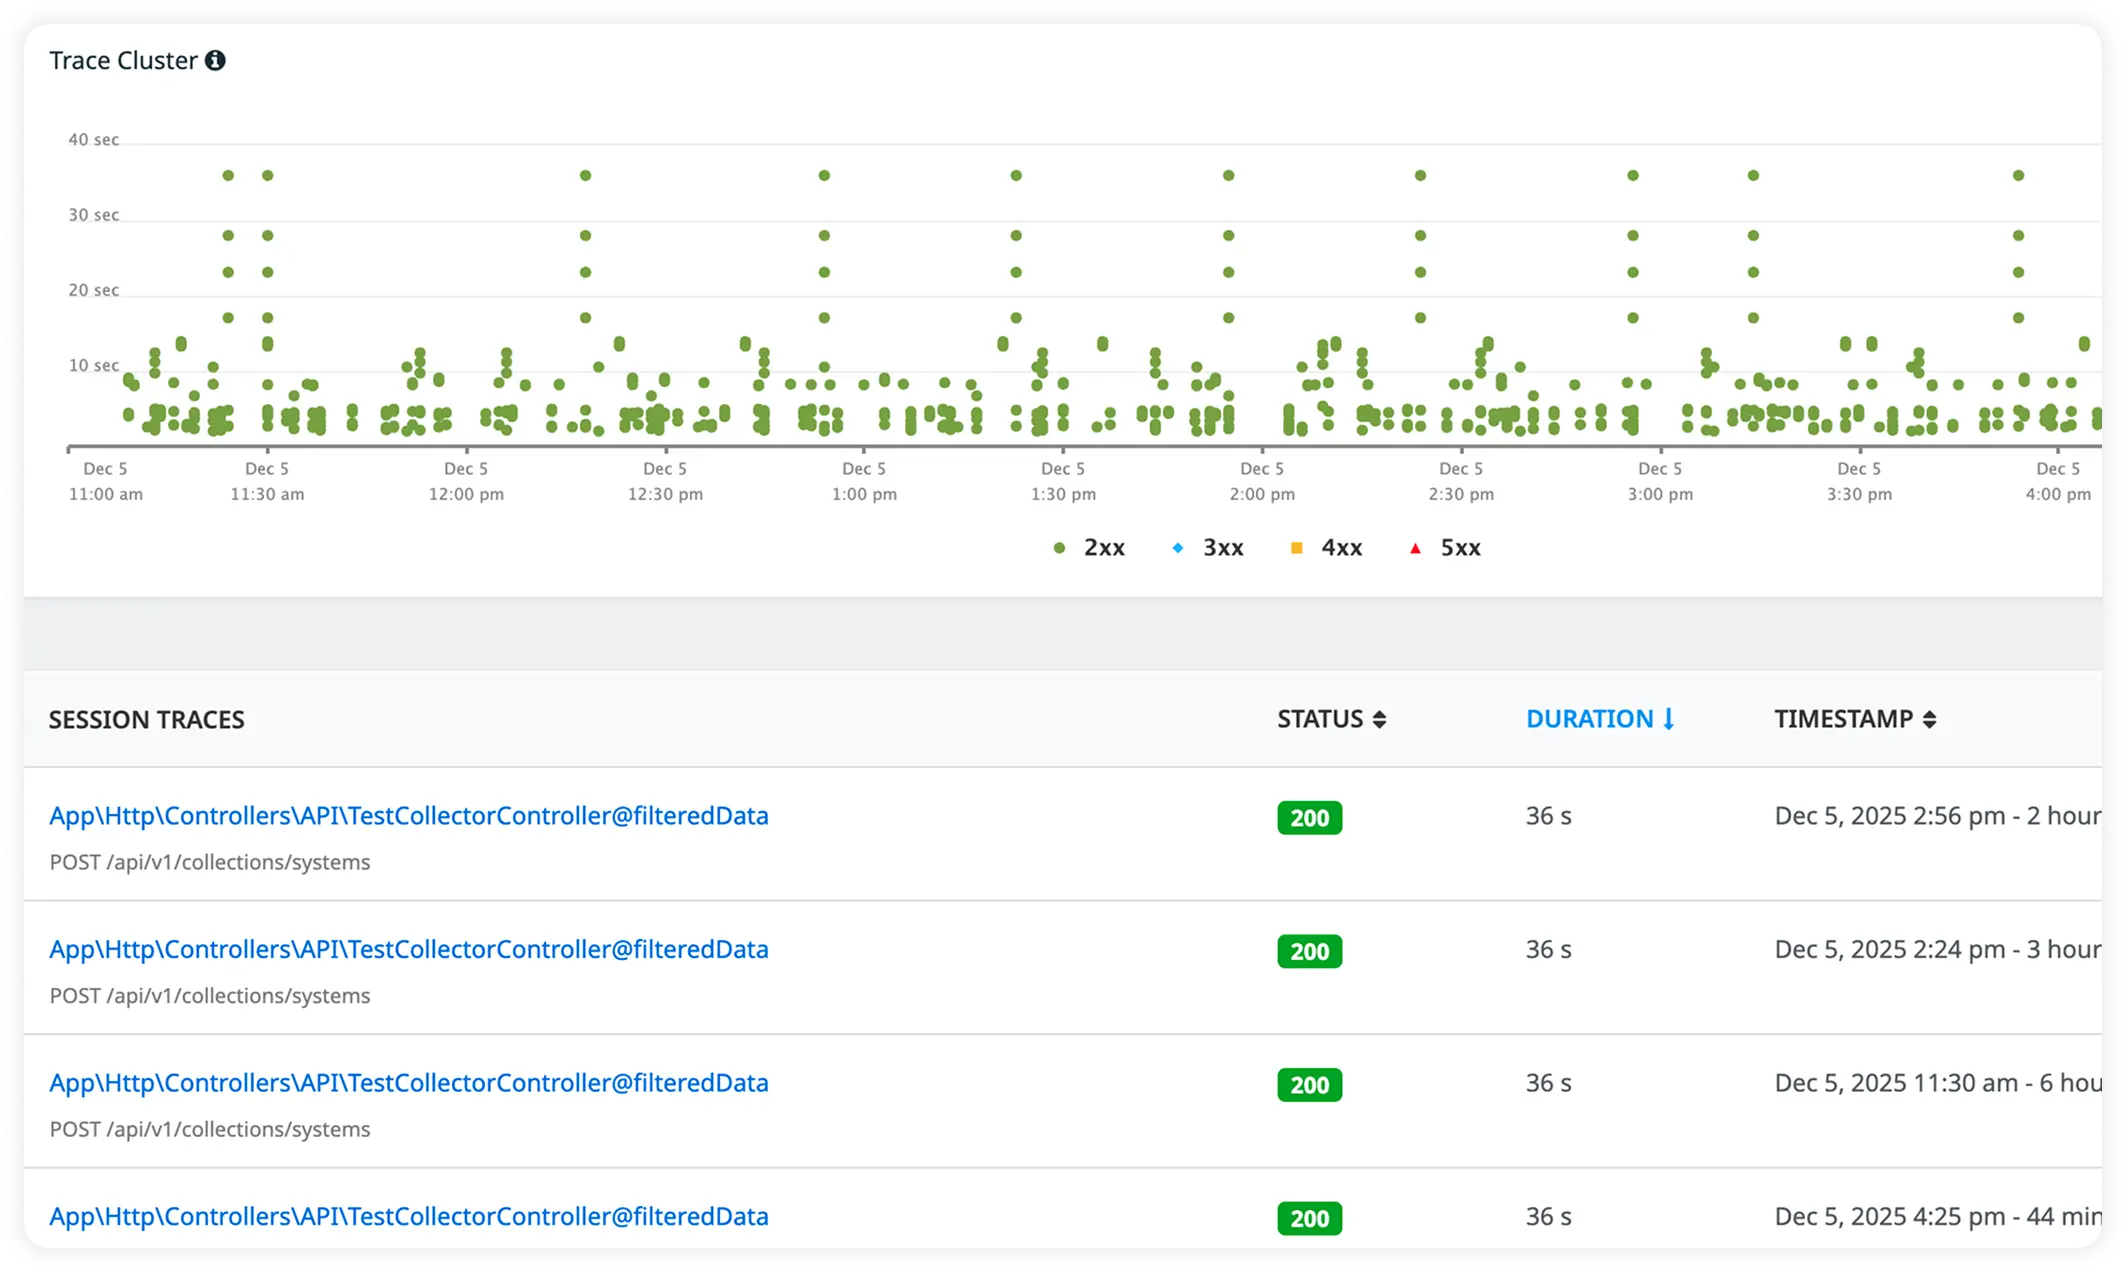
Track each request through services, APIs, databases, and background workers in a single distributed trace. Gain clear visibility into execution flow and performance behavior across your Python application.
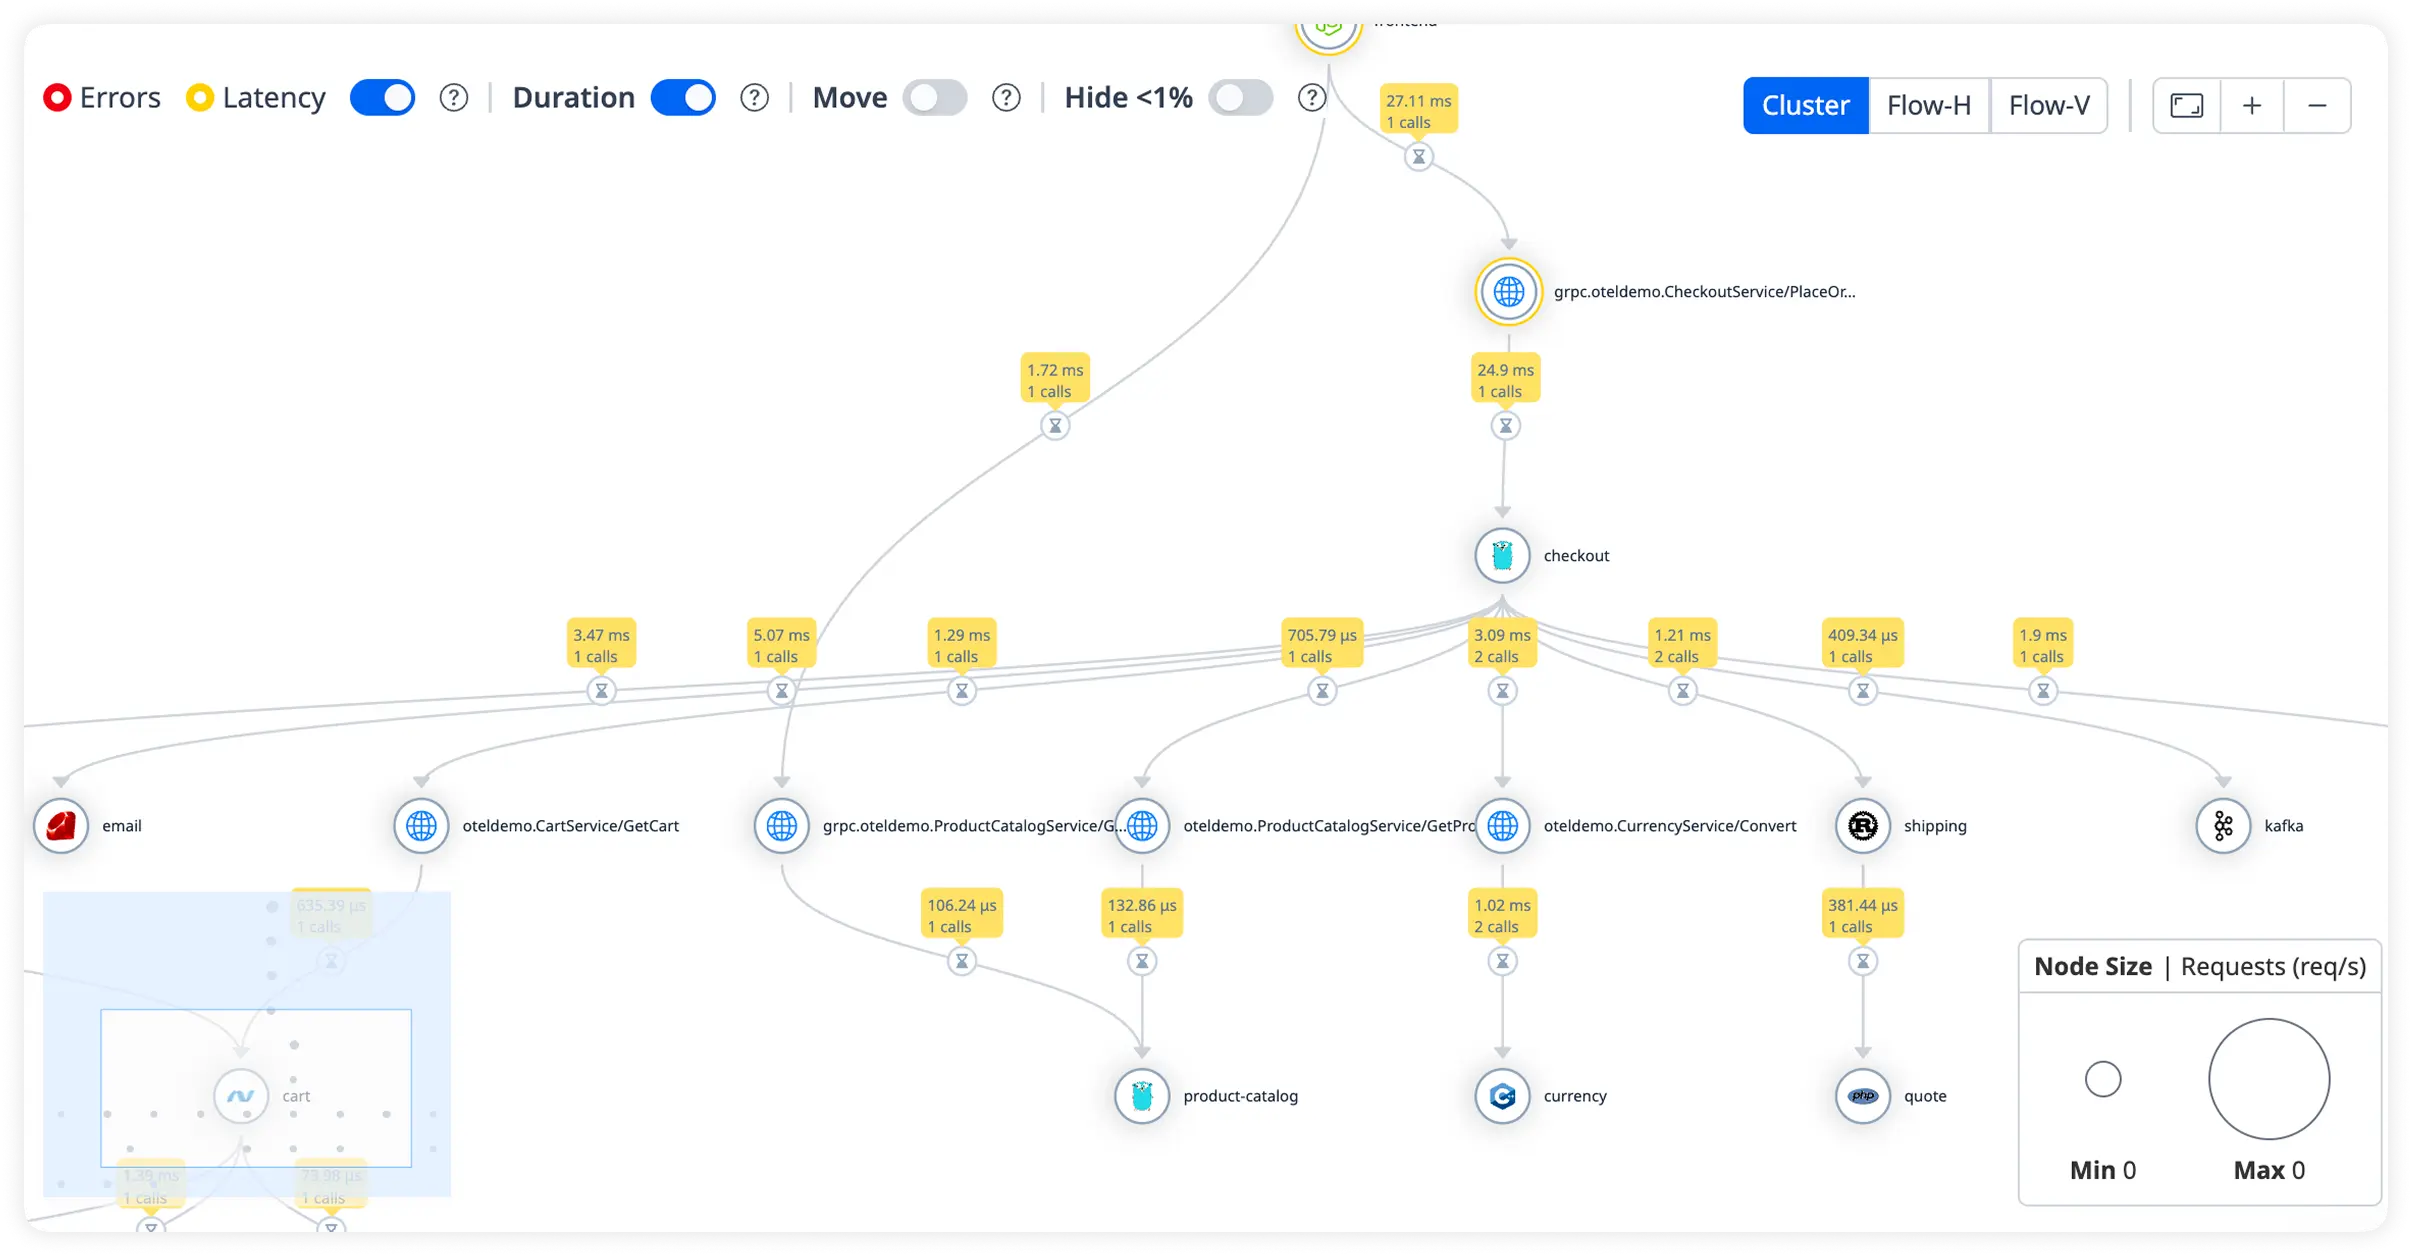
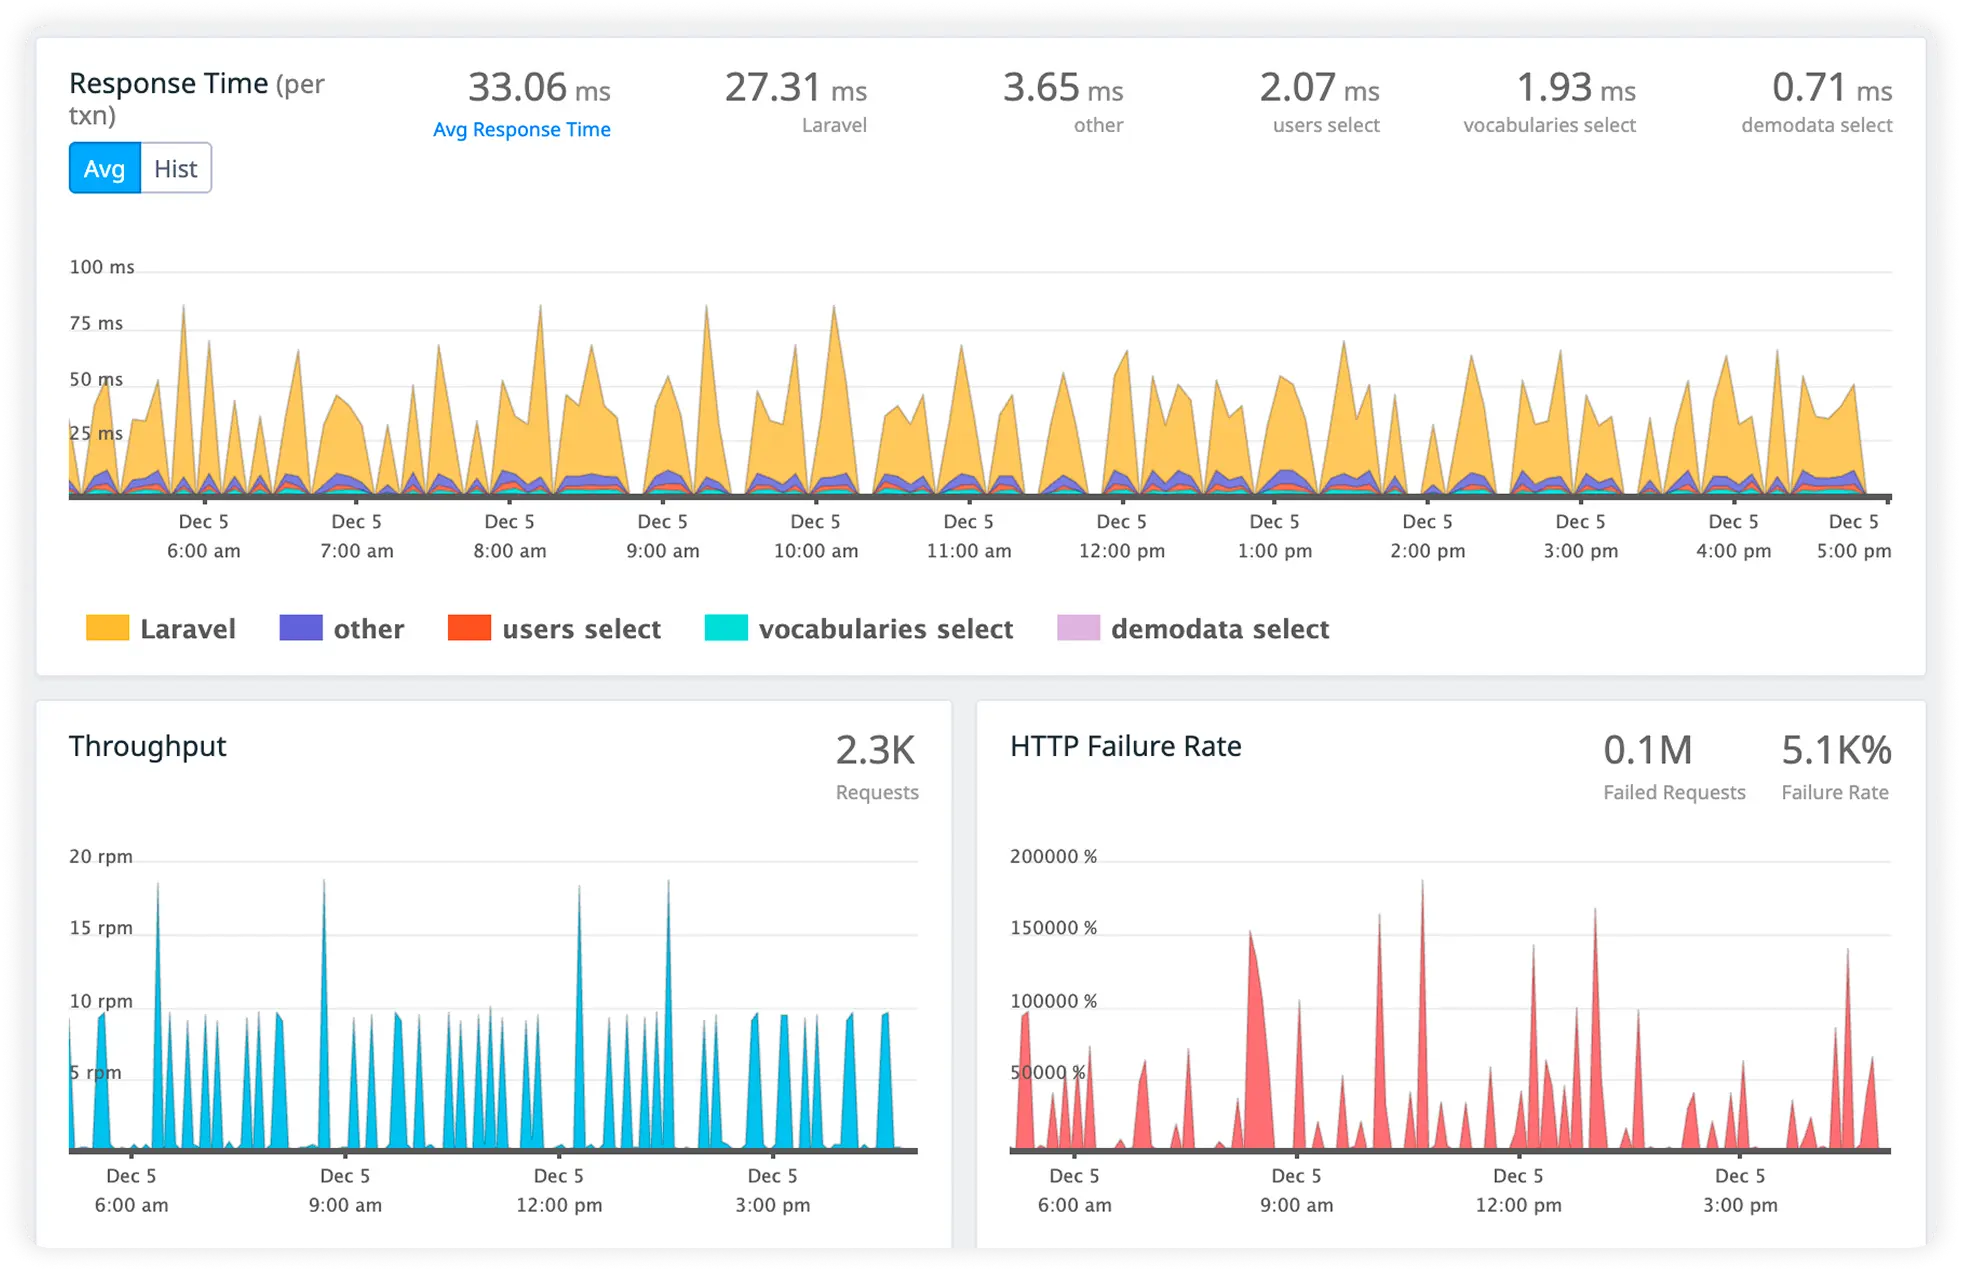
See how Python services connect with databases, message queues, caches, and third-party APIs. Quickly uncover latency patterns, failure points, and performance bottlenecks.
Monitor high-impact operations like data processing, authentication, API calls, and scheduled jobs. Spot slow transactions, error spikes, and performance regressions before users are affected.
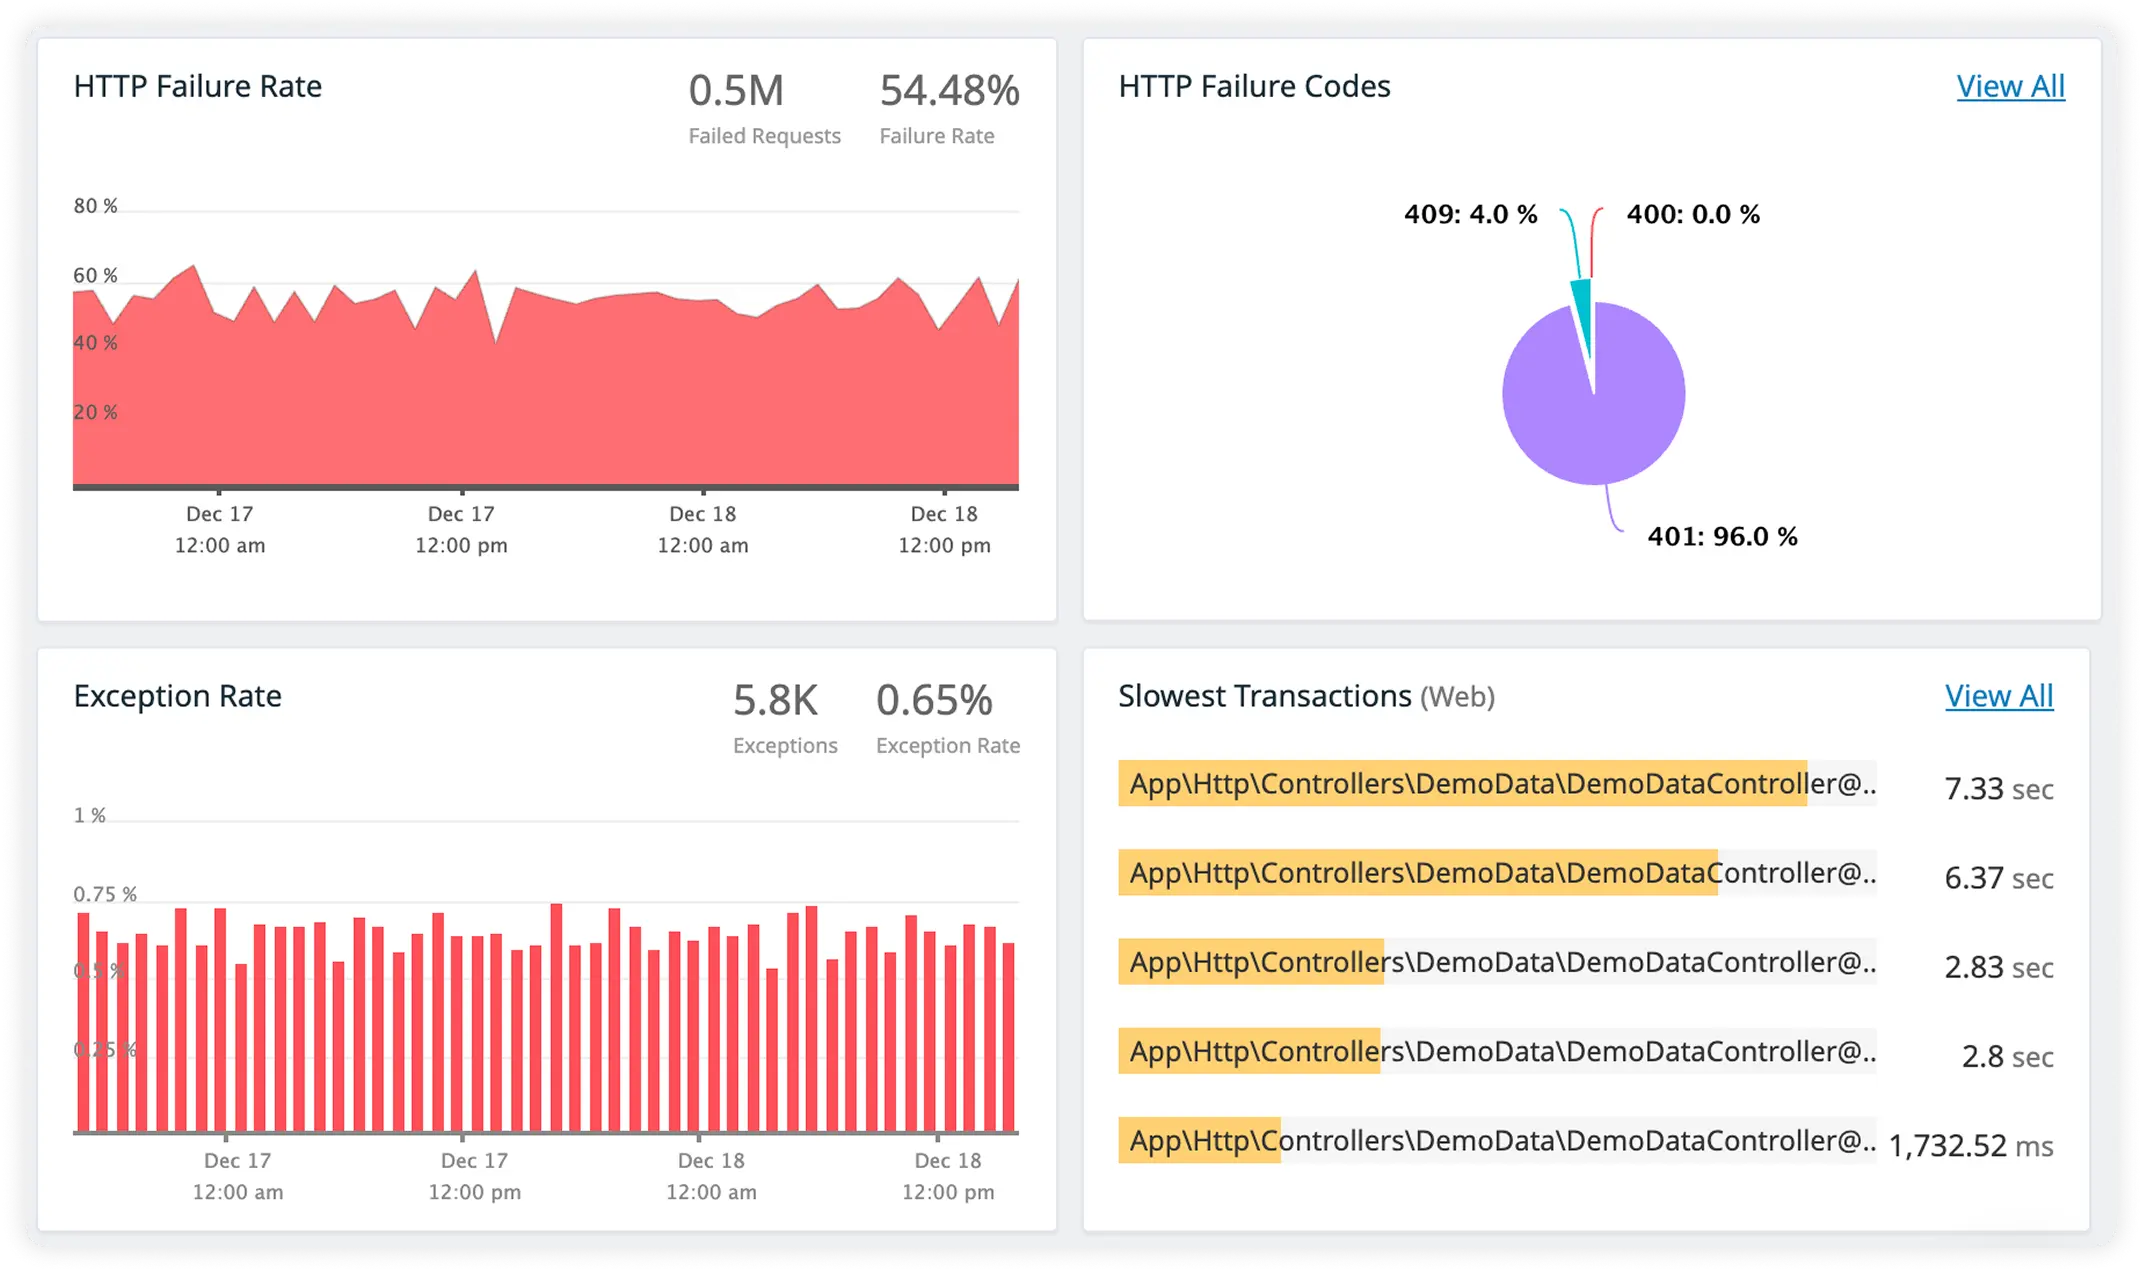
Track third-party dependencies and integrations your Python applications rely on. Detect outages and slow responses early to protect overall application performance.
Atatus fits teams that value directness and accuracy. It integrates into engineering workflows without changing how teams think or work.
Teams want to understand how their Python systems behave in reality, not how they are supposed to behave. Atatus aligns observed behavior with how engineers think about execution.
Platform and backend teams value tools that fit naturally into existing workflows. Engineers can reason about production behavior without long onboarding cycles.
Engineers trust what they see because the system reflects real execution, not sampled guesses or partial views.
SREs rely on signals that reflect real system state. Atatus earns confidence by presenting data that matches what engineers see during incidents.
Decisions in production should be evidence-driven. Atatus helps teams move from assumptions to concrete understanding when something feels off.
When failures occur, teams need immediate context. Atatus supports faster incident response by grounding discussions in shared, reliable information.
Backend, and SRE teams need a shared view of reality. Atatus helps reduce debate and aligns teams around the same operational truth.
Teams ship faster when they trust production. Atatus reinforces confidence by making system behavior understandable under real workloads.
Teams want sustained insight into how systems evolve. Atatus supports continuous understanding as architectures and traffic patterns change.
Atatus adapts to how engineering teams work across development, operations, and reliability.
Debug errors and slow paths with the full context of what happened.
Atatus for developersTrack deployments and see how each release affects stability.
Atatus for DevOpsWatch latency and error rates to ship with less production risk.
Atatus for release engineersPricing, deployment, data and the agent. If something is missing, a person will answer it on a demo call.
The Python performance monitoring tool helps developers to optimize the Python server performance.
A good Python APM solution answers the following two questions:
You can easily use application performance monitoring tools to answer, detect and resolve the above issues before they could impact the end users.
In general, there are two types of monitoring:
Every organization should have a well-implemented Python APM solution, which allows DevOps teams (and the organization as a whole) to resolve issues and performance bottlenecks efficiently and reduce Mean Time To Resolution (MTTR). This has a substantial impact on the bottom line of the business.
Now organizations do not have to deal with the unnecessary work involved in maintaining an extensive software analysis group.
Your Python performance monitoring tools should be easy to use, offer actionable insights, and be able to:
Technical Benefits:
Business Benefits:
With the help of the database monitoring, you can easily identify the database performance bottlenecks.

