You can now see what your AI features send to a model, what comes back, how long it takes and what it costs. LLM monitoring traces every LLM call your application makes and turns token usage into cost, so you can debug bad answers and keep spend under control.
LLM monitoring is part of the Atatus Python agent from version 2.1.0. Each call is recorded with its provider and model, such as OpenAI, Azure OpenAI, Anthropic Claude or Google Gemini, which helps developers, DevOps engineers and SREs who run chatbots, copilots or agents in production.
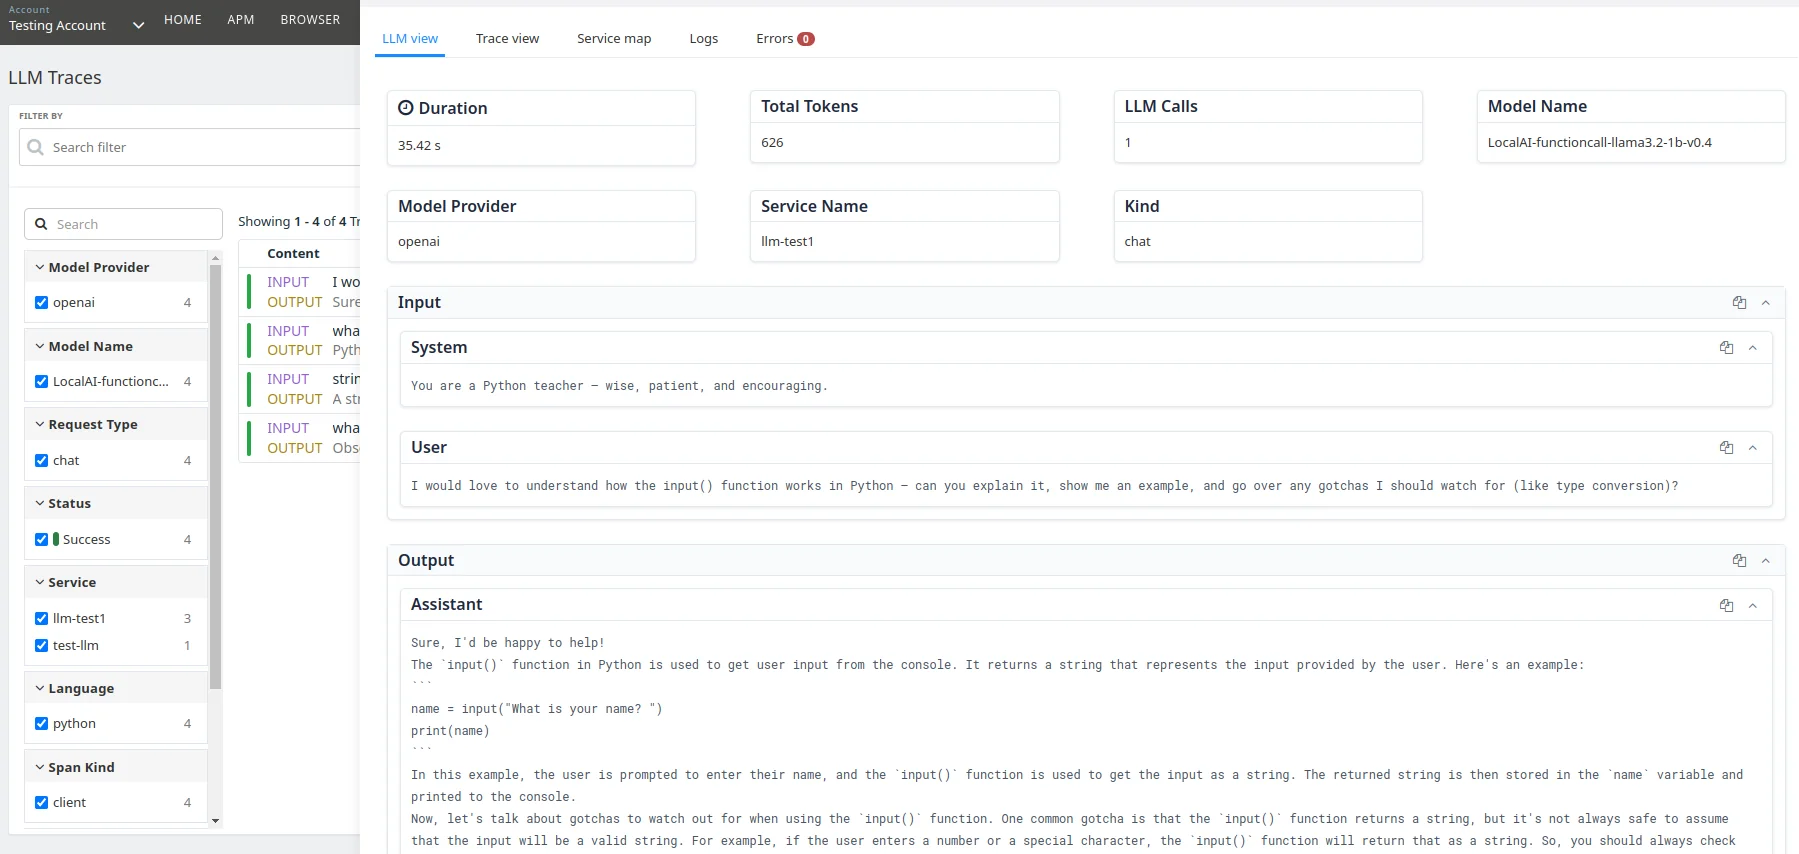
What you can do
- Prompts and responses: Read the input and output of every call to see why the model gave a particular answer.
- Step-by-step traces: Follow each step of an agent or chain as its own span, with its duration, tokens and the documents a retrieval step returned.
- Token cost: See tokens and cost per request, per model and per day to find what drives your spend.
- Model comparison: Compare requests, tokens, latency, cost and error rate across models.
- Failed calls: Filter traces by status, model, provider or service to find failed calls quickly.